
From Human Intent to AI agent Behavior: Yanice Yang’s Approach to Generative AI
The AI product designer and human-computer interaction (HCI) researcher combines research on creating interfaces with diffusion models, designing AI agent behavior, and carefully testing models to make AI design more focused on people.
Ask an AI tool to change a headline, and it might also rearrange the page. Ask it to make an image simpler, and it might add an extra object. These problems happen because a person's request must be turned into instructions that a generative AI system can understand, while keeping the parts of the work that the person wants to preserve.
Yanice Yang works on solving this problem. Her work in generative AI design connects the information given to models, the way AI agents behave, and the tools people use to review and change results. She designs how a user's intentions pass through the system and tests what happens when the model receives them.
Yang leads AI product design and has graduate training in human-computer interaction at the University of Michigan and a fine-arts background from Pratt Institute. She brings research, visual judgment and prototyping together in her work. This includes research she coauthored for IEEE conferences on creating interfaces with diffusion models and on computer vision, as well as collaborative AI design projects recognized by MUSE and Vega.
Her practical goal is to reduce cognitive load, which means the mental effort people spend understanding, guiding and correcting AI results. People should be able to explain what they want without learning special prompt-writing rules. They should understand what the AI thinks they mean and correct the result without starting the whole request again. Yang works toward this goal by making careful choices about context, limits, feedback and testing.
Turning visual ideas into instructions for AI models
A person may know which photographs create the right mood but find it hard to describe that mood in words. Giving a model every available reference can cause another problem: the examples may suggest different or conflicting ideas. Yang's work on visual guidance looks at both what the user starts with and what information the model receives.
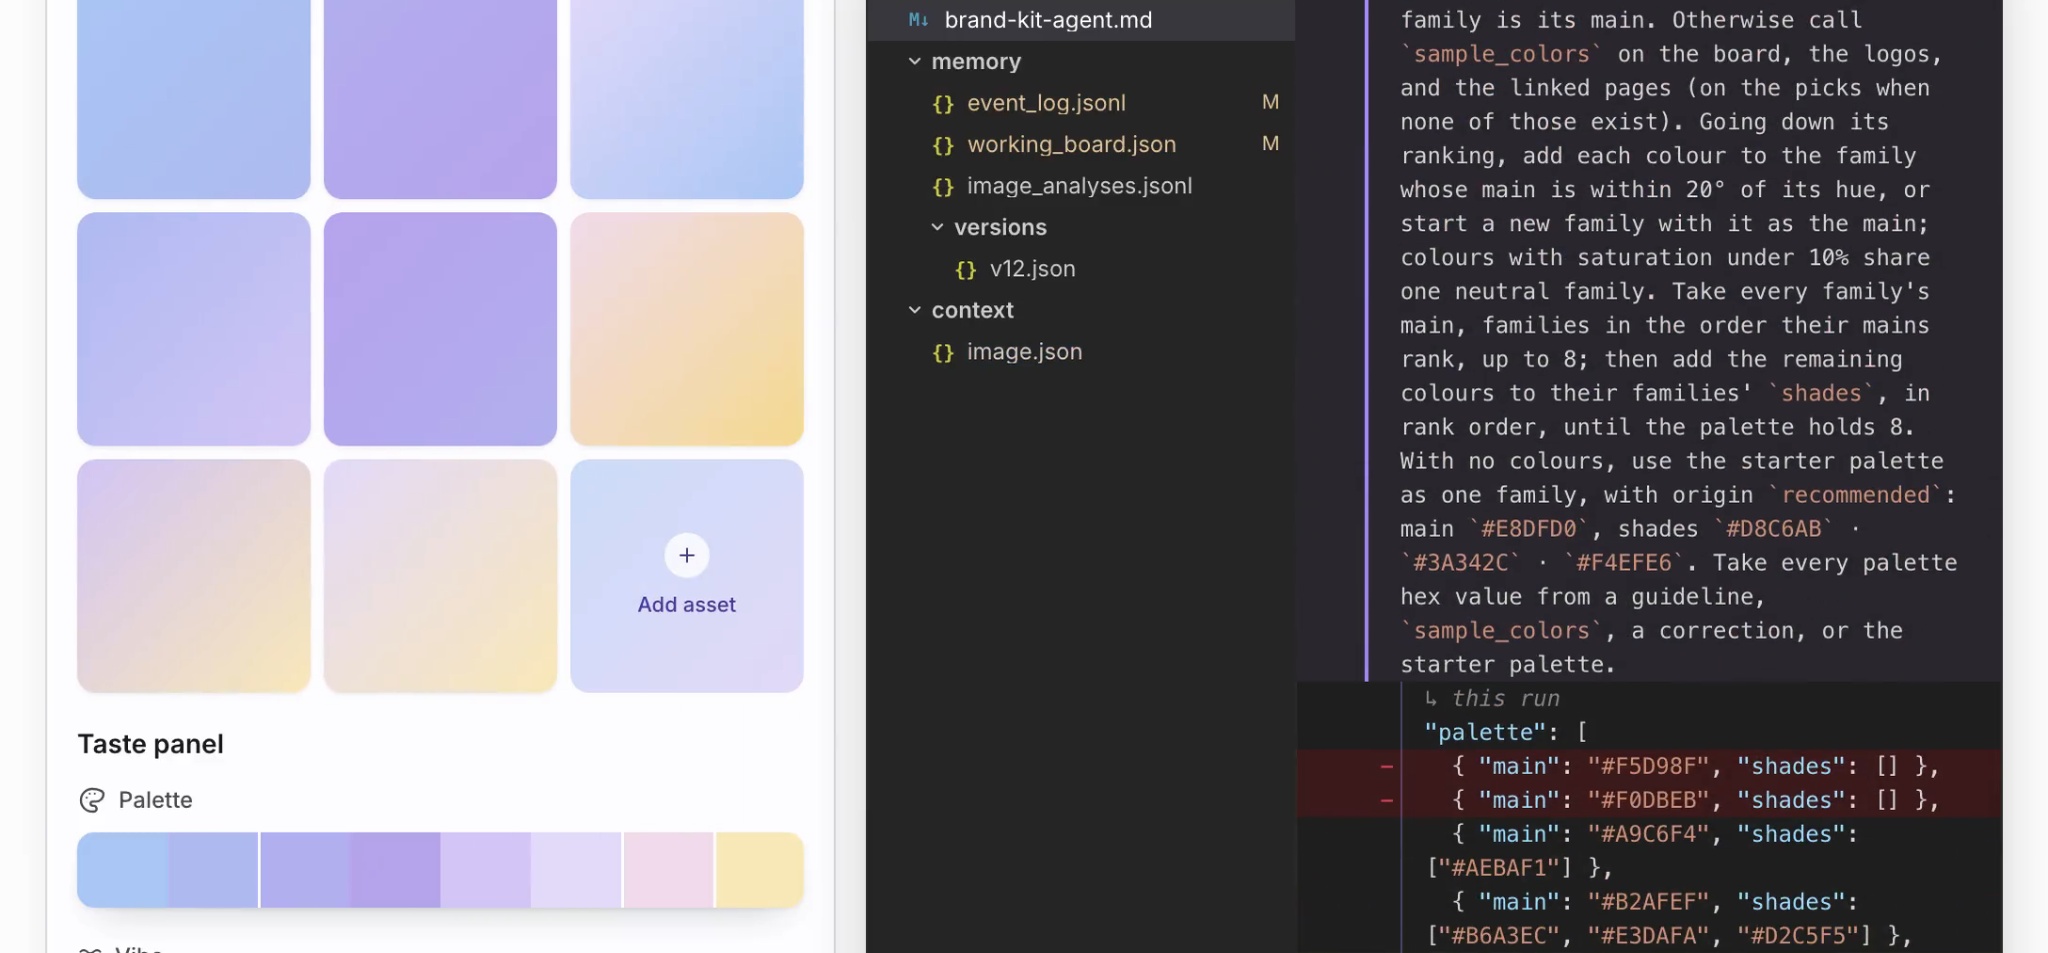
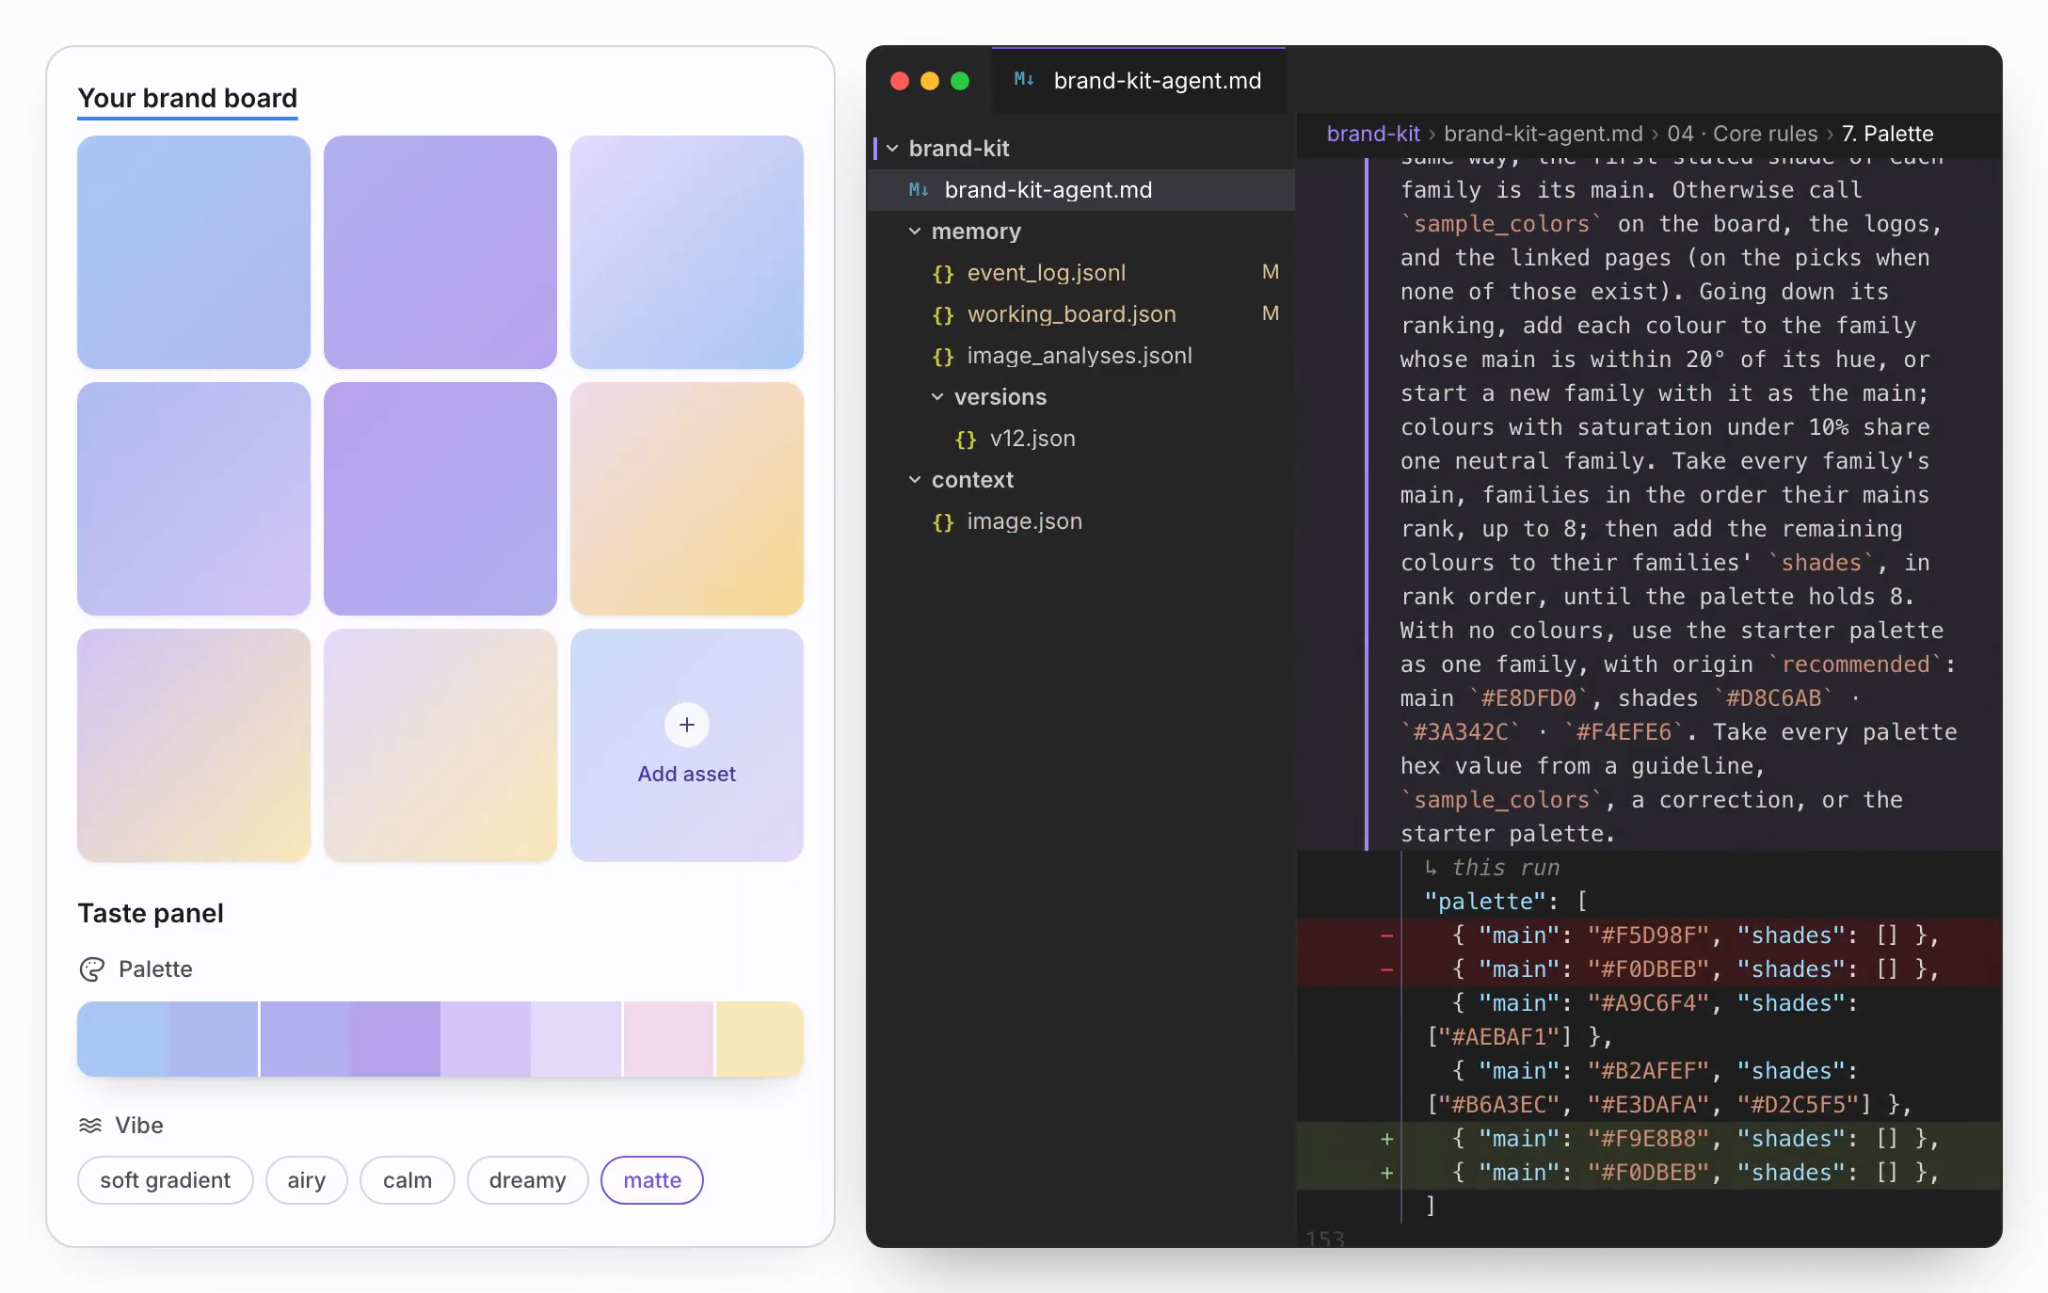
She designed a board with up to nine visual references and a review panel showing colors, visual details and examples of tone. The board gives people clear choices. They can keep an image, remove it or replace it with one that better matches what they want. The panel lets them check how the system understands their choices.
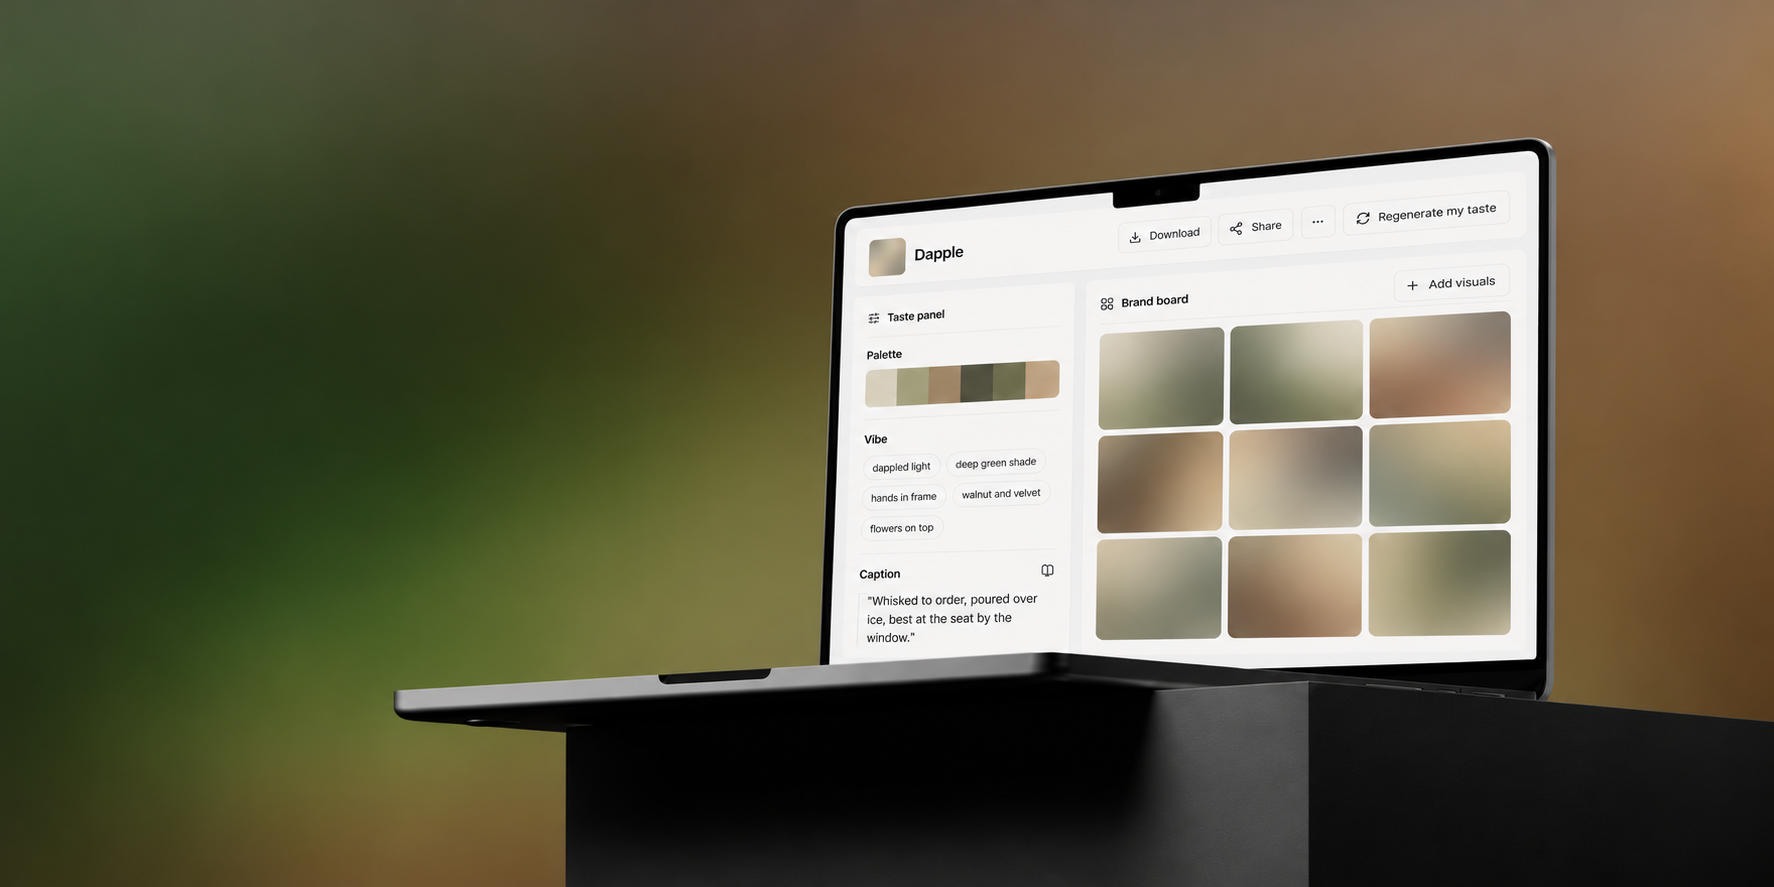
Behind this interaction, Yang defines how the reviewed examples are turned into an organized visual plan and color guidance for image generation. Short tags give users a quick summary of the direction, while the generation system receives a more detailed plan. This difference matters because a label that people can recognize and an instruction that helps a model do its job serve different purposes.
Her code-based demonstration connects changes to a reference image with changes to the related color palette, visual plan and saved versions of the context. This lets collaborators examine how the interface relates to the instructions behind it. The prototype makes the proposed behavior clear enough to study before people depend on it.
Yang uses this approach to reduce the effort users need to express their preferences while making the technical instructions more precise. People can show what they like through examples, and the system receives clearer guidance about how to use those examples.
Studying how feedback changes AI-generated results
The same goal appears in research she coauthored under the name Liuqingqing Yang, which she uses for her academic work. Her paper, Automated UI Interface Generation via Diffusion Models: Enhancing Personalization and Efficiency, studies a system that combines written descriptions and sketches with design rules and interactive feedback.
In this system, users' requirements guide the interface that the model creates. Rules about layout, color and spacing help organize the result. Users can then provide feedback to improve it. Together, these features address a practical challenge for generative AI: making something that people can guide and correct.
Researchers in other academic and industry teams have also discussed Yang's research. In Not Another EHR, researchers from Microsoft Research, the University of Washington and Stanford discuss her study of diffusion-based interface generation as part of their work on AI-generated healthcare interfaces. Their proposed system would let doctors ask for patient information in everyday language and receive a view arranged around their clinical needs. Another challenge is measuring the quality of AI-generated results. CANVAS, a benchmark developed by KAIST, Korea University and Yonsei University, discusses the same paper when reviewing evaluation methods. It tests whether models can recreate screens and make specific changes, such as resizing or adding interface components, using tools in Figma.
In work beyond design software, the focus shifts to understanding people's actions. Gestura, a project involving China Telecom's TeleAI and Goertek, discusses Yang's coauthored study on convolutional neural networks (CNNs) as background for gesture recognition. Experiments with its prototype AI glasses test gestures that express intentions such as changing the air-conditioning temperature, turning pages and taking photos. Her CNN research also appears in YOLOv8n-RF research on controlling smart TVs through cameras. A study published in MethodsX about an assistive communication prototype refers to her DeepSORT paper while exploring how a small set of gestures can be turned into text or actions. These independent discussions connect her research to a problem she also tackles in product design: turning human intentions into system actions that people can understand and control.
Yang has also carried out in-depth research on visual tracking and reviewed papers for Engineering Applications of Artificial Intelligence. Her judging and review work covers both academic and industry settings. This includes student design reviews at the University of Michigan and serving on judging panels for the Orpetron Web Design Awards and Top Design King. She has also judged several AI hackathons, including the AI Solution Makers Hackathon, where she assessed projects involving AI agents, automation and system reliability.
Setting clear rules for AI agent memory and revisions
When an AI workflow carries information from one task to another, a correction can affect more than the current screen. Changing the color of one image may be a temporary choice. Changing the overall visual direction may be something the user wants to keep for future work. An AI agent needs clear rules for telling these situations apart.
Yang's agent specifications distinguish between changing an individual asset and suggesting an update to guidance that should last. They define which information takes priority, how corrections from the owner are kept, and when a person must decide whether a suggested change should be saved for future use. In the workflow she designs, generation tools read the existing context, but updating that context follows a separate process.
When updates are approved, they become new profile versions. The system keeps the supporting evidence and history of corrections so people can track how the guidance changed. Reviewers can suggest changes, but the owner decides whether to accept them. Earlier results keep the context they originally used instead of silently changing to match a later preference.
Her specifications also cover missing or conflicting information. If information is missing, a value is uncertain, or a request does not fit an existing field, the system needs to handle the problem clearly. In these cases, the workflow may need more information or a decision from a person.
For image edits that affect only a selected area, her specifications pair the requested change with instructions about what must stay the same. Selecting an area by its coordinates can tell the system where to focus, but it cannot guarantee exactly which pixels will change. Yang includes review and version recovery so users can inspect the actual result and return to an earlier version if needed.
The intended benefit is that users can keep their work consistent without constantly supervising the AI. An approved preference can guide future creations, while a one-time adjustment stays limited to the current task. Yang designs the rules that help the system tell these two cases apart.
Testing whether a model follows the instructions
A tone selector is useful only if its choices produce language that sounds meaningfully different. Yang studied this in a controlled test of 720 AI-generated captions. The test covered five tones, four business categories and four tasks under three different prompt conditions.
The test used GPT-4o mini to create the captions and GPT-4o to judge their tone in comparisons where five choices were presented in a shuffled order. Instructions that used broad descriptive adjectives produced 45 percent tone separability. A structured set of phrases reached 88 percent, and a later version of that set reached 89 percent. These numbers measure how clearly the tones differed in those controlled comparisons judged by AI.
The phrase sets included expressions to use, expressions to avoid, example sentences and a hint about sentence style. The findings helped shape a design in which users could review and adjust language choices and examples. Instead of relying on one unclear adjective, the familiar tone setting would have more specific guidance behind it.
A separate image-generation test showed why evaluation must also look for unwanted changes. In a controlled comparison using gpt-image-1, a pixel-based measure of the background gave one version a score of 1.00. However, a GPT-4o vision evaluator preferred that version in only nine out of 24 comparisons between pairs of images. Looking closely at the results showed that an instruction meant to simplify an image could cause the model to add an object.
Yang recommended changing the prompt control. The difference between the measurements revealed a design problem that the high score had missed: someone who asked for a simpler image might end up with another object to remove. Testing the instruction behind the control gave her evidence to improve the interaction.
For Yang, evaluation helps improve the interface. A tone control can show example language that users can examine, while an image control can be changed if its instructions create extra work. Testing helps the design team decide what users can reasonably expect the product to do.
Keeping people in control of AI-generated video
In video creation, the key question is when automation should let the creator make a decision. An AI model can find useful footage and put clips together, but the creator still needs to decide whether the video tells the intended story.
Yang's work on turning footage into video covers product planning, workflow design, interaction design and prototyping. She works with product, research and development, design and machine-learning teams. Her case study describes research based on more than 500 survey responses from active users and reviews with over ten users. The findings showed that people welcomed AI help but wanted a draft they could change and improve.
She organized the experience into four stages: finding footage, choosing clips, creating a storyboard and editing the voiceover. Each stage gives creators a clear way to make changes. They can review the original footage, rearrange the sequence or adjust the narration. A/B tests with more than ten users examined design choices at these decision points.
This design reduces the need to generate the entire video again and again by making important parts of the draft editable. Creators can focus on the part that needs work while keeping the overall goal in mind. Yang decides where AI assistance is useful and what controls people need when the result is uncertain.
Yang's collaborative AI design work includes a concept for generative video editing that won Platinum in Conceptual Design–Technology at the 2024 MUSE Design Awards. Sonic AI, a concept for an at-home concert experience credited to Yang and two collaborators, won Gold in UX–Product at the 2025 Vega Digital Awards. These awards add to the research, specifications and tests that document her work.
Across these projects, Yang's leadership in product design connects what people want with how generative AI systems behave. The interface lets people express or change their choices. The agent's rules determine how those choices move through the system. Testing checks whether the model follows them. Each part affects how much work users still have to do.
Highlights
HCI and generative interface research: Research that Yang coauthored for IEEE conferences is cited in studies of AI-generated healthcare interfaces, AI design evaluation and wearable gesture interaction. These include work involving Microsoft Research, KAIST and China Telecom's TeleAI. Her studies examine how systems understand input, follow design rules and respond to feedback. These are also important questions in her AI product design work.
AI product and agent design: Yang leads product planning, workflow design, interaction design and prototyping. She defines how visual references become instructions for models, how agents tell temporary edits apart from lasting preferences, and when users can review or approve changes.
Model testing and user control: Yang uses controlled tests of captions and images to check whether models follow the intended direction and to improve the instructions behind interface controls. Her video workflows give creators clear opportunities to review footage, choose clips, change a storyboard and edit narration.