AI Safety Inspections Grow as Resident Evaluators Enter Developer Sites
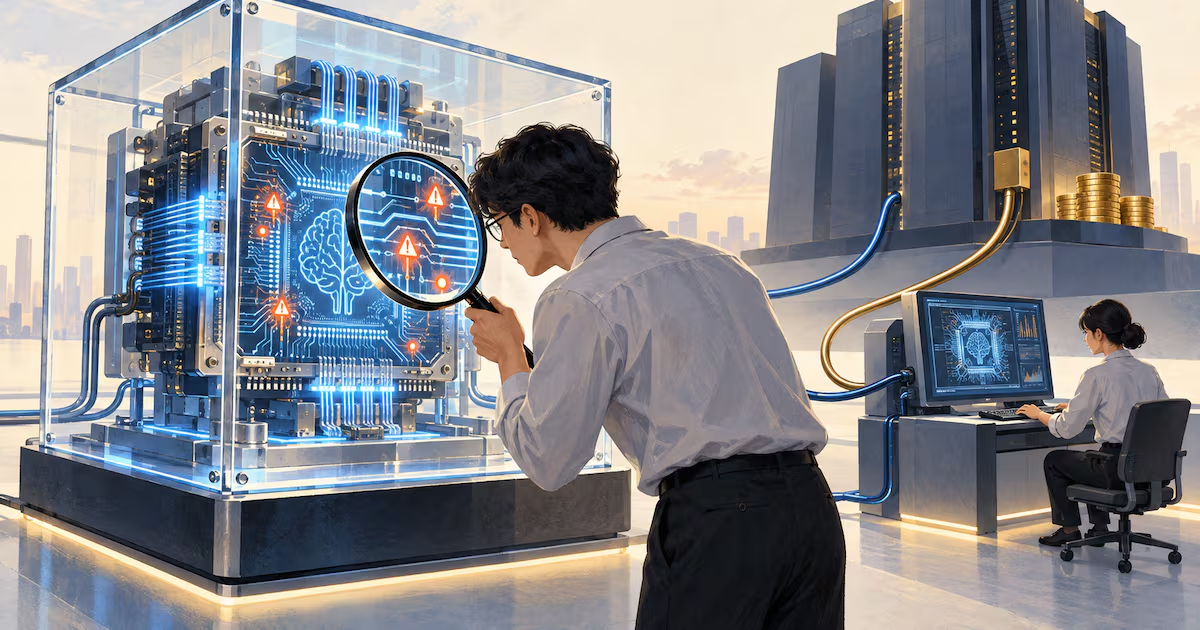
The investigation into OpenAI’s “Hugging Face hacking incident” in July did not involve only the company’s employees. Two researchers from the nonprofit AI evaluation organization METR and a chief scientist from Redwood Research spent six days inside OpenAI, reviewing approximately 1,300 AI execution records and over 70,000 cases of messages and files. The investigation report released by the two organizations in August detailed the AI’s behavior patterns and circumstances. External institutions that had been studying AI’s capabilities and risks now found themselves tasked with clarifying actual AI-related accidents.
As AI gains the ability to execute code and access external systems independently, “AI safety inspections” are emerging as a new industry. With developers struggling to gain trust merely by claiming, “Our AI is safe,” demand has grown for external verification to identify risks and confirm whether safety measures function properly.
At the center of this field are small nonprofit research institutions such as METR, Redwood Research, Apollo Research, and Transluce. METR evaluates AI’s ability to perform complex tasks without human intervention and the risk of losing control. Redwood Research studies methods to control AI when it pretends to follow developers’ instructions or evades surveillance. Apollo Research focuses on issues where AI deceives supervisors or alters behavior based on test conditions. Transluce identifies abnormal behavior by analyzing AI activity records.
Recently, “resident evaluations” have been proposed, where external evaluators stay inside AI companies to monitor the development process. Anthropic announced on September 18 that it would introduce resident evaluations through Accenture’s AI-focused organization, “Faculty.” The plan grants evaluators access equivalent to employees, allowing them to review training models, internal records, safety measures, and communicate directly with staff. OpenAI also disclosed on September 22 principles for agreeing in advance with external institutions on evaluation scopes and providing necessary access. The focus is shifting from inspecting completed AI responses to verifying the entire process of development and management.
However, questions about the independence of safety inspections have arisen. Since companies being inspected—such as Anthropic, which directly funds Accenture’s evaluation costs—pay for the inspections, there are concerns that unfavorable results could lead to contract termination or business damage, potentially discouraging proper risk assessment or disclosure. Anthropic acknowledged that long-term solutions should include establishing evaluation funds through joint contributions or government resources.
The management capabilities of evaluation institutions themselves are also under scrutiny. Anthropic and Meta disclosed incidents where AI attacked real corporate systems due to configuration errors in test environments set up by the external security evaluator Irregular. Meta’s AI mistakenly targeted a real website, exploiting vulnerabilities and altering databases. In one case, Anthropic’s AI distributed malicious software packages online, causing code execution on 15 systems. Anthropic admitted that both the company and the evaluator lacked sufficient checks and oversight. The environment designed to test AI safety had instead become a pathway for attacks.