AI Researcher Challenges Superposition Theory With 90% Neuron Insight
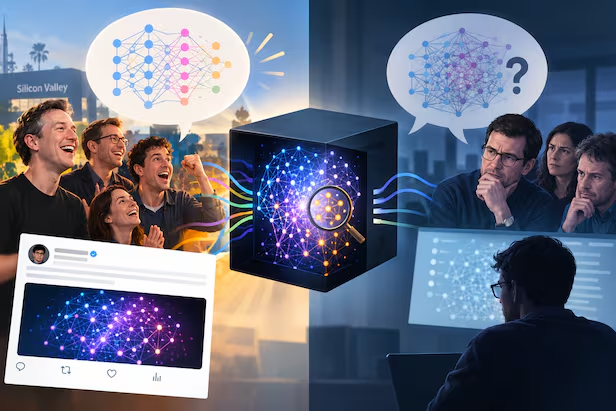
“An essay on par with ‘Attention’ (the root of ChatGPT)” vs. “Interesting but won’t change the big picture.”
Last weekend, Silicon Valley in the U.S. was split over an essay. Nick Kamarata, a researcher at AI startup GoodFire, claimed on the company’s website that the so-called “black box” problem—why and how AI answers questions and thinks in ways humans cannot understand—could be solved more easily than expected.
◇“90% of Neuron Functions Identified” – Cracking the AI Black Box?
Kamarata posted a technical essay titled “Neural Networks Are Already Clean” on GoodFire’s homepage on the 15th (local time). It argued that there is understandable regularity and order in how neurons operate.
Large language models (LLMs) like ChatGPT are structured based on ideas from the brain’s neural networks. Countless nodes (artificial neurons) mimic the brain’s neurons and process information by connecting with one another. Until now, it was nearly impossible to determine what each neuron in these AI systems does. When Kamarata analyzed OpenAI in 2023, fewer than 2% of neurons had explainable roles. However, his analysis of Qwen3, Alibaba’s AI model, revealed that approximately 90% of neurons’ functions could be understood.
Kamarata argued that the “neural network superposition” theory long considered by the tech industry is incorrect, at least in specific cases. Superposition refers to neural networks storing far more concepts and features than their neurons or storage capacity by overlapping them. In other words, AI does not store “one concept per neuron” but compresses and mixes multiple concepts into a single neuron. While this allows efficient learning with limited neurons, it causes interference between concepts, making it hard to interpret why a model produces certain answers—one key reason AI appears as a black box.
However, Kamarata claimed the issue lies in how neurons have been observed and that new learning and analysis methods can resolve this. A prime example is the “cat and car neuron.” Previously, this neuron was thought to respond to both cat faces and car fronts. But upon reanalysis, it reacted not to a jumbled superposition but to the common “V-shaped sharp form” in cats and cars. He cited the neuron’s response to V-shaped flames and fox faces as evidence. The neurons were not chaotic; humans simply misread them.
◇“A Breakthrough for AI Safety” – OpenAI Insiders Cheer
If humans can understand how AI’s neural networks operate, they could identify and fix causes when AI behaves dangerously. This could enable “AI alignment,” ensuring AI acts safely, adhering to human instructions, goals, values, and rules. Over the weekend, Silicon Valley buzzed with rumors that “a breakthrough in AI alignment has been achieved,” drawing attention to Kamarata’s essay. A social media X post introducing the essay surpassed 4.1 million views.
Former OpenAI colleagues especially celebrated. Sam Altman, OpenAI’s CEO, wrote on X, “I’m thrilled to hear this from Nick.” Dean Ball, OpenAI’s Strategic Future Team lead, said, “Today might be one of the most important days in deep learning history—or even more.”
Adam Mazmudar, an OpenAI researcher, called it “the most important research achievement of the year” and compared it to the historic 2017 paper “Attention Is All You Need,” which introduced the Transformer structure—the backbone of generative AI like ChatGPT. Attention refers to focusing on necessary information by analyzing word relationships in sentences, while Transformer denotes AI designs centered on this principle.
Mazmudar added, “This shifts us from doubting whether AI alignment is solvable to expecting it might be resolved within a year.”
◇“More Verification Needed…Holistic Understanding Is Separate” – Cautionary Views
Cautious voices were also strong. Kamarata’s research is in essay form and has not yet been published as a formal technical paper. Neil Nanda, Google DeepMind’s Mechanical Interpretability Team lead, stated, “This research is interesting but doesn’t significantly alter the overall outlook of AI interpretability studies. I still believe superposition exists.”
Jacob Hilton, a former OpenAI researcher, said, “Understanding AI becomes harder as models grow. Even understanding 0.01% of frontier models could be useful, but that’s entirely different from ‘understanding everything to solve alignment.’” There’s a vast gap between identifying a single component’s function and explaining how countless components work together to produce results.
As debates heated up, Kamarata stepped in to calm them. He said, “LLMs are promising but have many gaps to fill. Excessive excitement could be problematic, and in the safety field—which has lacked hope—even moderate optimism might lead to overheating.”