
SC26: HyperAccel to Showcase LPU-Based AI Inference System
Highlighting power and cost efficiency, based on 8-LPU servers
This is a press release edited by StorageNewsletter.com on November 17, 2026, at 2:00 pm.Summary:
- An eight-LPU server system and a live remote demonstration of LLM processing running on working servers in Korea.
- Internal tests show more than 3.5 times higher token processing per watt and per dollar than systems using NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs.
HyperAccel, a South Korean company that designs AI chips and focuses on making large language model (LLM) processing more energy-efficient, will showcase its LPU (LLM Processing Unit) technology at SC26 (Supercomputing 2026). The event will take place from November 17 to 19 at McCormick Place in Chicago. 
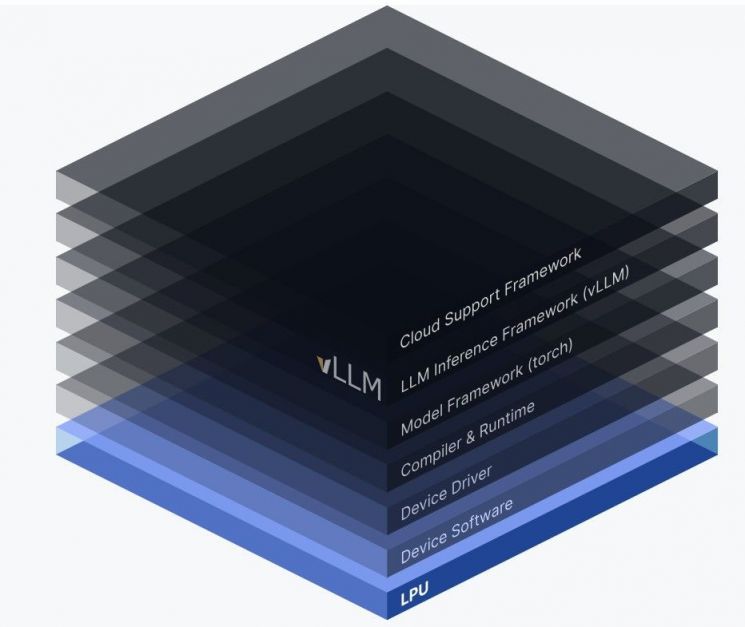
At the exhibition, HyperAccel will show how its LPU technology works as part of a complete server system, rather than just as individual chips. This will show how the technology can be used in real AI systems. During a live remote demonstration from its servers in Korea, visitors will see LLM processing running on working equipment. They will also learn how the technology could be used by businesses and in data centers.
According to HyperAccel's internal tests, a server using HyperAccel LPU cards, each with a power rating of 250W, processes more than 3.5 times as many tokens per watt and per dollar as a similar system using NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, each rated at 600W. These tests used the Qwen3-32B and Llama3-70B models. HyperAccel's LPUs also support larger LLMs, including Kimi and GLM models. The company says its technology could make LLM processing more energy-efficient and less expensive, making it a possible solution for business AI systems and data centers.
These efficiency improvements come from the way HyperAccel designed its LPU specifically for LLM processing. The chip uses LPDDR5X memory, which needs less power, together with HyperAccel's Streamlined Dataflow architecture. This design uses about 90% of available memory bandwidth. GPUs typically use 50% to 60%. The higher use of memory bandwidth helps reduce power use and running costs when processing large numbers of AI requests.
Alongside its main exhibition, Joonyeon Kim, CFO of HyperAccel, will give a presentation called “Redefining AI Infrastructure Through Token Efficiency” at Lablup Inc.'s booth (#4630) on November 18, from 2:30 pm to 2:45 pm Central Time.
By taking part in SC26, HyperAccel hopes to build its presence around the world and help more organizations adopt LPU-based systems for AI processing. The company is looking to work with server manufacturers, cloud service providers, and companies that provide AI infrastructure solutions around the world. It is interested in integrating its technology into server platforms, testing and confirming how well it works, and developing business opportunities in global data center markets.
“As AI adoption accelerates, the industry is shifting its focus from raw processor performance to the efficiency and economics of AI inference at scale,” said Joo-Young Kim, CEO of HyperAccel. “At SC26, we are excited to showcase how our purpose-built LPU architecture delivers superior token efficiency at the server level, reducing the cost and power consumption of AI inference. We also look forward to engaging with global infrastructure partners to bring more efficient and scalable AI solutions to market.”
Visitors can meet the HyperAccel team at the AI Semiconductor Korea Pavilion, booth #1411. They can learn about its LPU technology, see the eight-LPU server system, and watch the live remote demonstration of LLM processing on working servers in Korea.
Event Information
- Event: SC26 (Supercomputing 2026)
- Date: November 17-19, 2026
- Venue: McCormick Place, Chicago, Illinois, USA
- HyperAccel booth: #1411, AI Semiconductor Korea Pavilion
- Exhibition: An eight-LPU server system and a live remote demonstration of LLM processing using working servers in Korea
- Presentation by Joonyeon Kim: November 18, 2:30-2:45 pm CT
- Presentation venue: Lablup Inc., booth #4630
